A redirect error in Search Console and a successful live test describe different observations. Before rewriting content or changing redirects, establish when each result was obtained and which request actually failed.
A November 1 Blogger Community report illustrates the question: a site owner described stored redirect errors alongside successful live checks and a mobile redirect to ?m=1. The owner could not reproduce a loop and had no failed-crawl server logs. This is an individual report, not a confirmed platform fault or evidence of an encoding problem.
One separate failure worth testing is address normalization. In an October 24 experiment, Marko Fedorenko reported that Google repeatedly received redirects while Chrome reached content. Keep that demonstrated mechanism separate from the unresolved Blogger report; a similar symptom does not establish the same cause.
Start with dated observations, then test address encoding
Write down the stored crawl date, live-test time, exact inspected URL and device context before comparing the results. A successful request today does not reconstruct a failed request from an earlier date. Preserve both observations and seek the missing historical chain instead of declaring either result wrong.
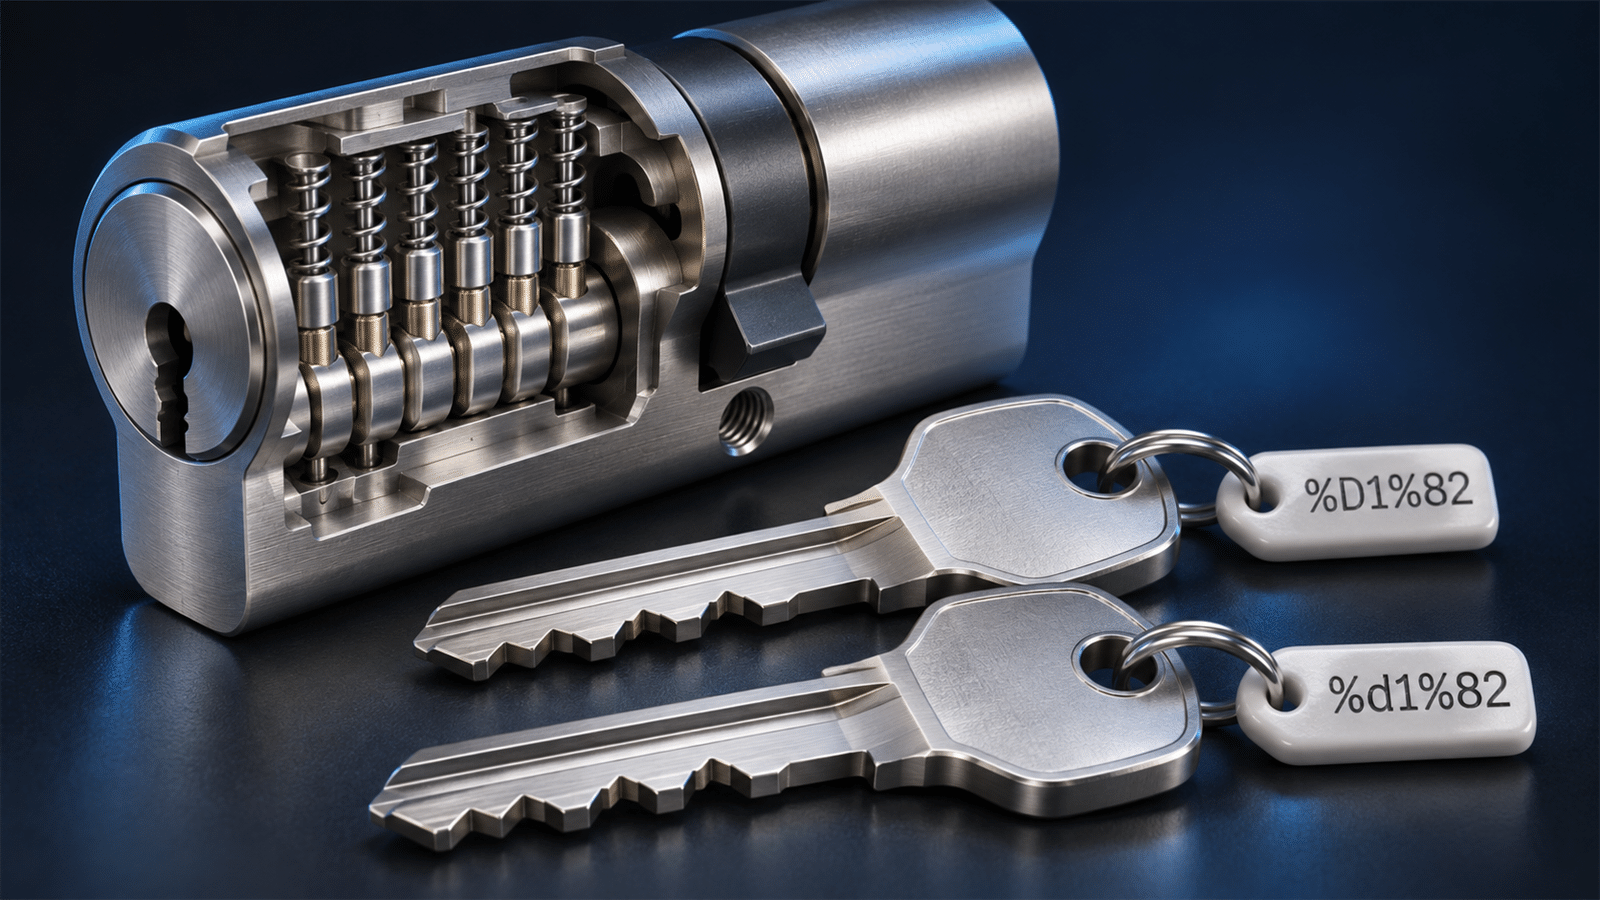
RFC 3986 treats the hexadecimal letters in percent-encoded bytes as case-insensitive. Thus %D1%82 and %d1%82 represent the same bytes. Changing D to d does not lowercase the Cyrillic letter those bytes encode. That distinction matters when a rule decides that every different raw string needs a redirect.
Google’s URL guidance separately warns that path case can distinguish addresses. That does not mean all parts of an address should be lowercased indiscriminately. Decide which paths the application regards as equivalent before implementing normalization; preserve values whose meaning depends on case.
Capture the response, not just the final browser view
Build a small test set from real pages: one plain Latin path, one Cyrillic path, one accented path and a URL containing an encoded reserved character if the site uses one. Add relevant query-string examples. This is a proposed diagnostic matrix, not a claim that every such address is broken.
For each entry, retain the exact encoded request, HTTP status, raw Location header and eventual destination. Test uppercase and lowercase hex representations. A redirect that changes only hex case is a warning to investigate, rather than proof by itself that the application has different content.
Request a destination without automatically following every redirect, then follow the chain with a finite limit. Prefer GET when checking the actual page response: a successful HEAD request alone does not establish what the content request receives. Save the evidence before changing the rule so the same requests can verify the repair.
Use logs to distinguish a crawler loop from a browser success
Look for repeated requests for the same normalized address that each receive a redirect instead of content. Compare their timestamps and destination headers with a controlled browser request. Verify crawler identity using Google’s published verification method; a Googlebot user-agent label alone is not authentication.
In the reported experiment, the interaction between server redirects and crawler normalization repeated the request, while the browser followed a form it could open. Your diagnosis should establish that sequence on your own stack. Check application, proxy and CDN rules together: two individually plausible transformations can disagree about the preferred representation.
Do not use a user-agent-specific exemption as the default repair. It can hide the underlying inconsistency and leave other clients exposed. The goal is a stable address policy that serves the intended page consistently.
Approve a repair with explicit acceptance checks
Ask the developer to define normalization at the URL-component level. Avoid blanket decoding and re-encoding: encoded separators such as %2F, signed parameters and application routing can need special handling. There is no safe universal replacement snippet for every stack.
Before release, require a stable successful destination for both equivalent encoding forms, a deliberate policy for genuinely different path case, preserved parameter values and no repeated chain. Then align internal links, sitemap entries and the canonical reference with that preferred destination.
After deployment, repeat the saved requests and inspect subsequent verified crawler responses. Successful fetching is the first milestone; it does not promise an indexing date or ranking recovery. This sequence keeps a transport defect from being mistaken for a content-quality problem or a slow canonical reassessment.
Sources
- Blogspot: GSC redirect error but live test succeeds; mobile 302 to ?m=1
- Як lowercase-редирект ламає індексацію URL з кирилицею та іншими не-ASCII символами
- URL structure best practices for Google Search
- RFC 3986: Uniform Resource Identifier (URI): Generic Syntax
- Redirects and Google Search
- Verify requests from Google crawlers and fetchers